NVIDIA L40S
The NVIDIA L40S is an enterprise-class GPU built on the Ada Lovelace architecture, featuring 48 GB of memory with 864 GB/s of memory bandwidth and a 350 W TDP. It delivers 91.6 TFLOPS of FP32 performance and 362 TFLOPS of FP16 tensor performance. Currently available from 10 providers starting at $0.67/GPU/hour, with a market median of $1.26/GPU/hour across 40 configurations.
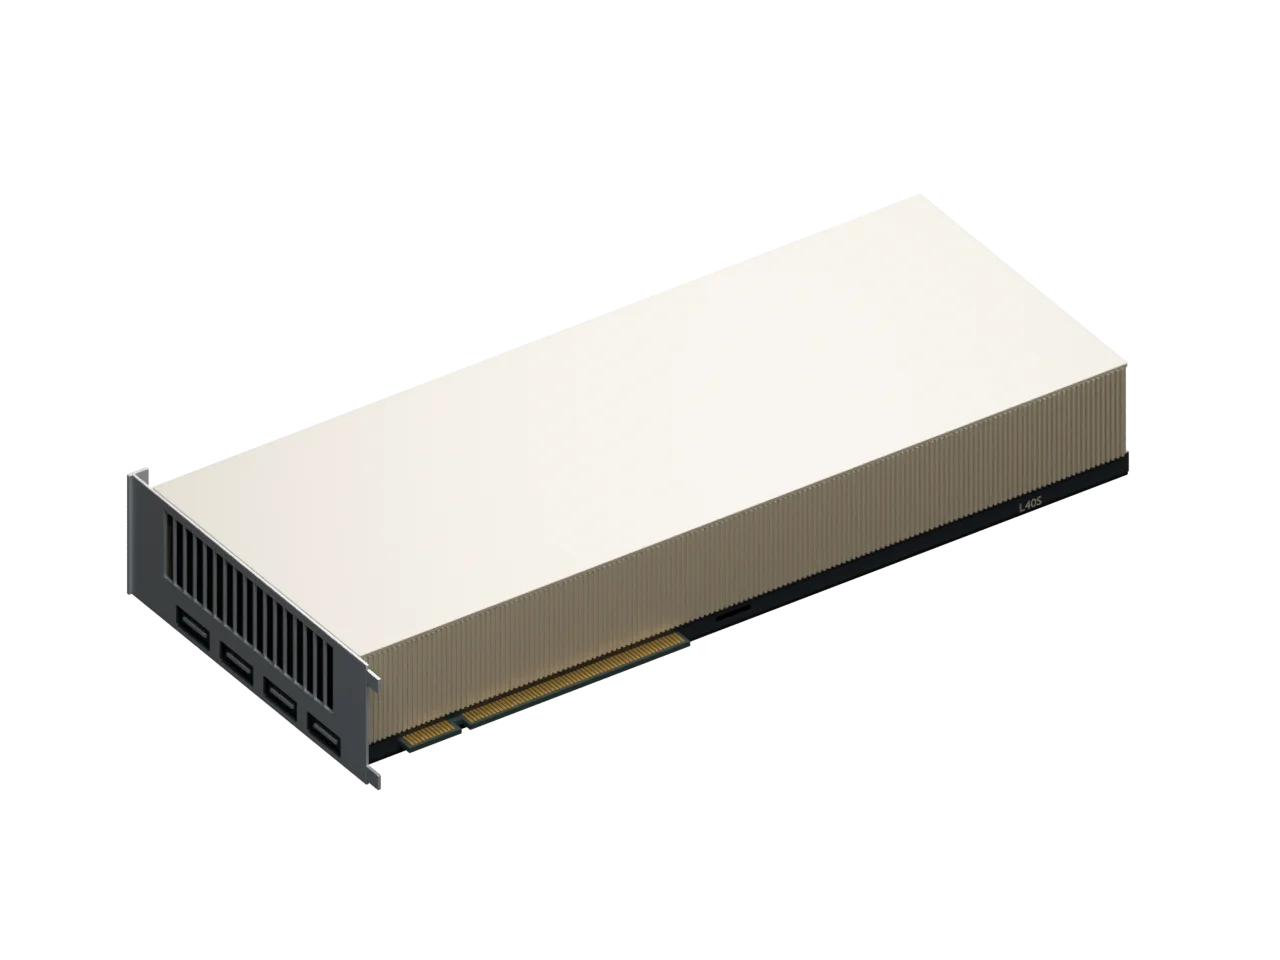
L40S · PCIe reference design
Representative design. Provider hardware may differ.
Hardware specifications
Same across all providers
Median price across all providers
11 offerings from 10 providers
Sorted by price ascending. Compare configurations side-by-side.
| Provider | Count | vCPU | RAM | Region | Per GPU hour | Total/hr | Action |
|---|---|---|---|---|---|---|---|
| ×1 | 16 | 94 GB |   | $1.090 | $1.09 | Launch | |
 Novita AIReferral link | ×1 | 22 | 125 GB |    +7 | $0.550 | $0.55 | |
| ×1 | 24 | 252 GB |    +3 | From$0.670 +1.3% 30d | From$0.67 | Launch | |
| ×2 | 44 | 256 GB |  | From$0.925 +70.3% 30d | From$1.85 | Launch | |
Up to$500credit | ×1 | 16 | 94 GB | | $1.090 | $1.09 | Launch |
| ×1 | 12 | 72 GB | | $1.140 +17.5% 30d | From$1.14 | Launch | |
Up to$1credit | ×8 | 64 | 1.5 TB | | From$1.253 -0.2% 30d | From$10.02 | Launch |
| ×1 | 16 | 180 GB | -- | From$1.560 | From$1.56 | Launch | |
| ×1 | 8 | 96 GB |  | $1.644 -3.5% 30d | From$1.64 | Launch | |
 Sesterce CloudReferral link | ×10 | 80 | 1.44 TB | | From$1.650 0.0% 30d | From$16.50 | Launch |
| ×1 | 20 | 60 GB | -- | From$1.662 +19.0% 30d | From$1.66 | Launch | |
| ×1 | 12 | 72 GB | | $1.800 0.0% 30d | From$1.80 | Launch |




LLMs that fit on the NVIDIA L40S
Estimated VRAM for popular open-weight LLMs at 16-bit (FP16/BF16), 8-bit (FP8/INT8) and 4-bit (INT4/MXFP4) precision, against 48 GB per GPU. Showing the 12 largest that fit.
| Model | Parameters | 16-bit | 8-bit | 4-bit |
|---|---|---|---|---|
| DeepSeek R1 DeepSeek | 671B 37B active | — Not released | 826 GB Too large | 481 GB Tight on 10× · 19% spare |
| DeepSeek V4 Flash DeepSeek | 284B | — Not released | — Not released | 192 GB Barely fits on 4× |
| Solar Open2 250B Upstage | 250B 15B active | 601 GB Too large | 330 GB 8× · 54 GB free | 192 GB 8× · 192 GB free or 4× · 19% spare |
| Qwen3 235B-A22B Alibaba | 235B 22B active | 564 GB Tight on 10× · 2% spare | 310 GB 8× · 74 GB free | 181 GB 4× · 11 GB free |
| Laguna-S 2.1 Poolside | 118B 8B active | 282 GB 8× · 102 GB free | 155 GB 4× · 37 GB free | 90 GB 2× · 5.7 GB free |
| gpt-oss-120b OpenAI | 117B 5.1B active | — Not released | — Not released | 78 GB 2× · 18 GB free |
| Qwen3.6 35B-A3B Alibaba | 35B 3B active | 86 GB 2× · 9.7 GB free | 47 GB Barely fits on 1× | 28 GB 1× · 20 GB free |
| Qwen3 32B Alibaba | 32.8B | 79 GB 2× · 17 GB free | 43 GB 1× · 4.8 GB free | 25 GB 1× · 23 GB free |
| Gemma 4 31B Google | 31.3B | 75 GB 2× · 21 GB free | 41 GB 1× · 6.7 GB free | 24 GB 1× · 24 GB free |
| GLM-4.7 Flash Z.ai | 31.2B | 75 GB 2× · 21 GB free | 41 GB 1× · 6.8 GB free | 24 GB 1× · 24 GB free |
| Qwen3.6 27B Alibaba | 27.8B | 67 GB 2× · 29 GB free | 37 GB 1× · 11 GB free | 21 GB 1× · 27 GB free |
| Mistral Small 3.2 24B Mistral AI | 24B | 58 GB 2× · 38 GB free | 32 GB 1× · 16 GB free | 18 GB 1× · 30 GB free |
Estimates: model weights plus 20% for KV cache and runtime overhead, at short context lengths. Long contexts and large batches need more. Rows marked “tight” hold the weights but not that full margin. A ×N figure is the total VRAM across N of these GPUs and makes no claim about interconnect throughput. How we estimate this · Start from a model instead
Want more from this page?
See incorrect data?