NVIDIA H100
The NVIDIA H100 is an enterprise-class GPU built on the Hopper architecture, featuring 80 GB of memory with 3,350 GB/s of memory bandwidth and a 700 W TDP. It delivers 67 TFLOPS of FP32 performance and 989 TFLOPS of FP16 tensor performance. Currently available from 17 providers starting at $1.30/GPU/hour, with a market median of $3.36/GPU/hour across 68 configurations.
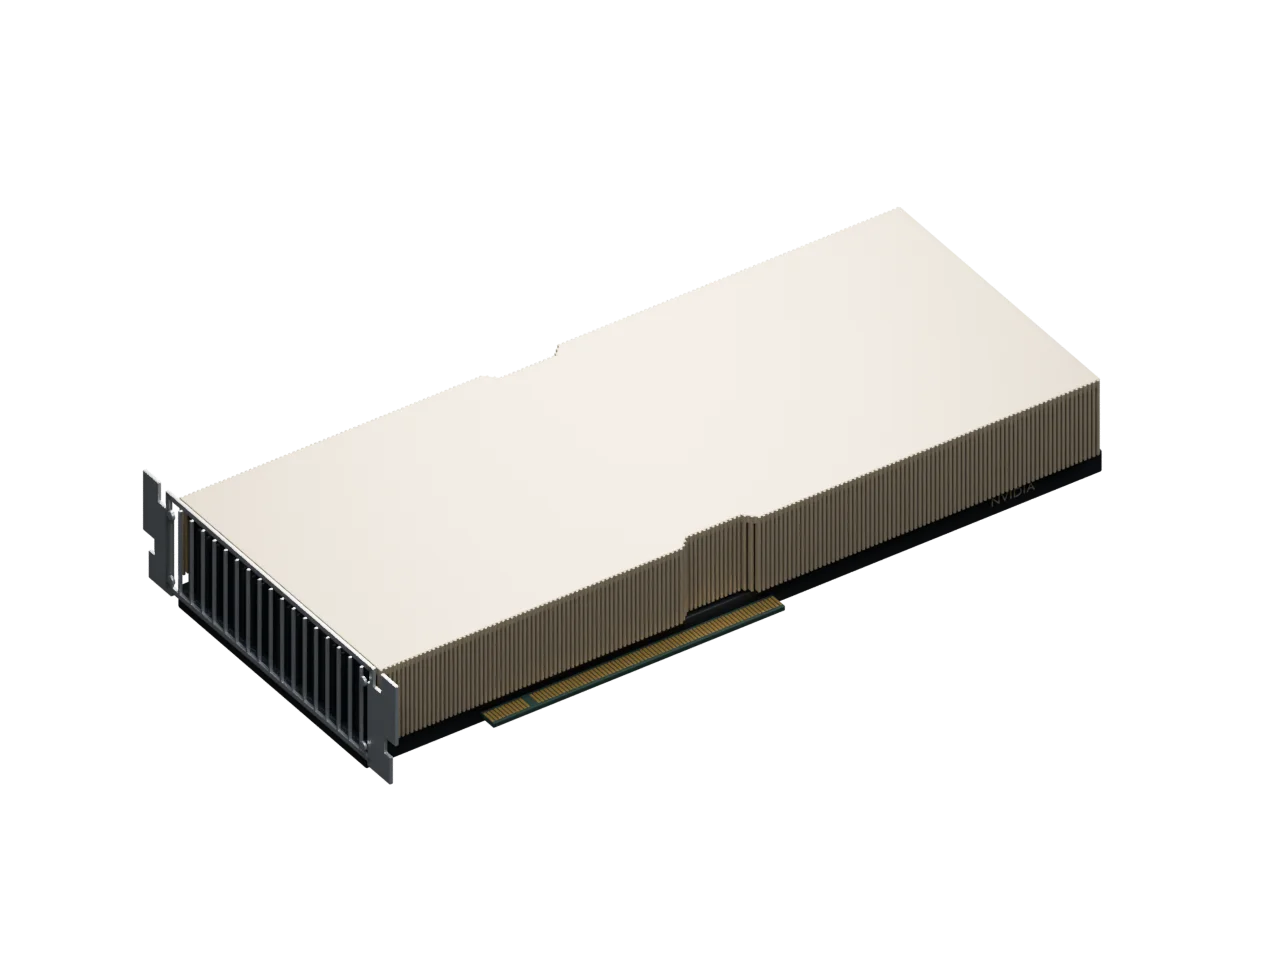
H100 · PCIe reference design
PCIe illustration. Listed configurations may use SXM or other variants.
Hardware specifications
Same across all providers
Median price across all providers
19 offerings from 17 providers
Sorted by price ascending. Compare configurations side-by-side.
| Provider | Count | vCPU | RAM | Region | Per GPU hour | Total/hr | Action |
|---|---|---|---|---|---|---|---|
| ×1 | 16 | 251 GB |  | $2.890 | $2.89 | Launch | |
Up to$5credit | ×1 | 20 | 236 GB |   | From$1.300 +1.6% 30d | From$1.30 | Launch |
| ×1 | 24 | 283 GB |   +2 | From$1.480 +7.5% 30d | From$1.48 | Launch | |
Up to$100credit | ×1 | — | — |  | $2.040 | $2.04 | Launch |
 Theta EdgeCloudTrending | ×1 | 10 | 80 GB | -- | $2.290 | From$2.29 | Launch |
| ×1 | 28 | 180 GB | | From$2.500 0.0% 30d | From$2.50 | Launch | |
| ×1 | 20 | 236 GB | | From$2.600 +32.1% 30d | From$2.60 | Launch | |
| ×1 | 28 | 180 GB | | From$2.630 +32.1% 30d | From$2.63 | Launch | |
Up to$500credit | ×1 | 16 | 251 GB |  +3 | From$2.890 | From$2.89 | Launch |
| ×1 | 20 | 128 GB | -- | From$3.000 | From$3.00 | ||
 Thunder ComputeReferral link | ×1 | 4 | 32 GB | -- | From$3.200 0.0% 30d | From$3.20 | Launch |
| ×1 | 24 | 240 GB |   | From$3.204 -3.8% 30d | From$3.20 | Launch | |
| ×1 | 28 | 180 GB | | $3.250 +48.4% 30d | From$3.25 | Launch | |
| ×1 | 26 | 200 GB | | From$3.290 0.0% 30d | From$3.29 | Launch | |
Up to$1credit | ×8 | 128 | 1.5 TB | | From$3.298 -2.0% 30d | From$26.39 | Launch |
 Novita AIReferral link | ×1 | 16 | 128 GB |  | $3.390 0.0% 30d | $3.39 | |
 OblivusReferral link | ×1 | 28 | 180 GB | | From$3.500 0.0% 30d | From$3.50 | Launch |
 Sesterce CloudReferral link | ×2 | 48 | 480 GB | | From$3.630 0.0% 30d | From$7.26 | Launch |
| ×1 | 30 | 120 GB | -- | $3.850 +17.9% 30d | From$3.85 | Launch | |
Up to$200credit | ×1 | Billed separately | Billed separately | -- | $3.950 0.0% 30d | From$3.95 | Launch |







LLMs that fit on the NVIDIA H100
Estimated VRAM for popular open-weight LLMs at 16-bit (FP16/BF16), 8-bit (FP8/INT8) and 4-bit (INT4/MXFP4) precision, against 80 GB per GPU. Showing the 12 largest that fit.
| Model | Parameters | 16-bit | 8-bit | 4-bit |
|---|---|---|---|---|
| Kimi K2.5 Moonshot AI | 1T 32B active | — Not released | — Not released | 714 GB Tight on 8× · 7% spare |
| GLM-5.2 Z.ai | 753B | — Not released | 994 GB Too large | 579 GB 8× · 61 GB free |
| DeepSeek R1 DeepSeek | 671B 37B active | — Not released | 826 GB Too large | 481 GB 8× · 159 GB free |
| DeepSeek V4 Flash DeepSeek | 284B | — Not released | — Not released | 192 GB 4× · 128 GB free or 2× · 0% spare |
| Solar Open2 250B Upstage | 250B 15B active | 601 GB 8× · 39 GB free | 330 GB 8× · 310 GB free or 4× · 16% spare | 192 GB 4× · 128 GB free |
| Qwen3 235B-A22B Alibaba | 235B 22B active | 564 GB 8× · 76 GB free | 310 GB 4× · 9.7 GB free | 181 GB 4× · 139 GB free or 2× · 6% spare |
| Laguna-S 2.1 Poolside | 118B 8B active | 282 GB 4× · 38 GB free | 155 GB 2× · 4.8 GB free | 90 GB 2× · 70 GB free or 1× · 6% spare |
| gpt-oss-120b OpenAI | 117B 5.1B active | — Not released | — Not released | 78 GB 1× · 1.7 GB free |
| Qwen3.6 35B-A3B Alibaba | 35B 3B active | 86 GB 2× · 74 GB free or 1× · 11% spare | 47 GB 1× · 33 GB free | 28 GB 1× · 52 GB free |
| Qwen3 32B Alibaba | 32.8B | 79 GB 1× · 1.4 GB free | 43 GB 1× · 37 GB free | 25 GB 1× · 55 GB free |
| Gemma 4 31B Google | 31.3B | 75 GB 1× · 4.9 GB free | 41 GB 1× · 39 GB free | 24 GB 1× · 56 GB free |
| GLM-4.7 Flash Z.ai | 31.2B | 75 GB 1× · 5.1 GB free | 41 GB 1× · 39 GB free | 24 GB 1× · 56 GB free |
Estimates: model weights plus 20% for KV cache and runtime overhead, at short context lengths. Long contexts and large batches need more. Rows marked “tight” hold the weights but not that full margin. A ×N figure is the total VRAM across N of these GPUs and makes no claim about interconnect throughput. How we estimate this · Start from a model instead
Similar GPUs
See more GPUs like this in
Want more from this page?
See incorrect data?